I’ve been comparing AI detection tools, and Clever AI Detector keeps appearing in recommendations. Has anyone tested its accuracy against other top AI detectors? I need a reliable option and would appreciate feedback based on real-world use.
What the accuracy claims leave out
The thing people keep getting wrong about AI detectors is treating performance on untouched ChatGPT text as meaningful proof of reliability. That is the easy case. Once someone rewrites, edits, paraphrases, or “humanizes” the text, the differences between detectors become much harder to ignore.
I ended up looking at GEDE, short for Generative Essay Detection in Education, a public research dataset from Lukas Gehring and Benjamin Paaßen at Bielefeld University. The researchers describe the work in the GEDE research paper, while the material needed to inspect or reproduce it is available through the GEDE code repository. The dataset includes human essays alongside text produced or modified by language models, with different degrees of AI involvement.
That distinction matters far more than another polished accuracy badge on a product page.
Where the detectors separated
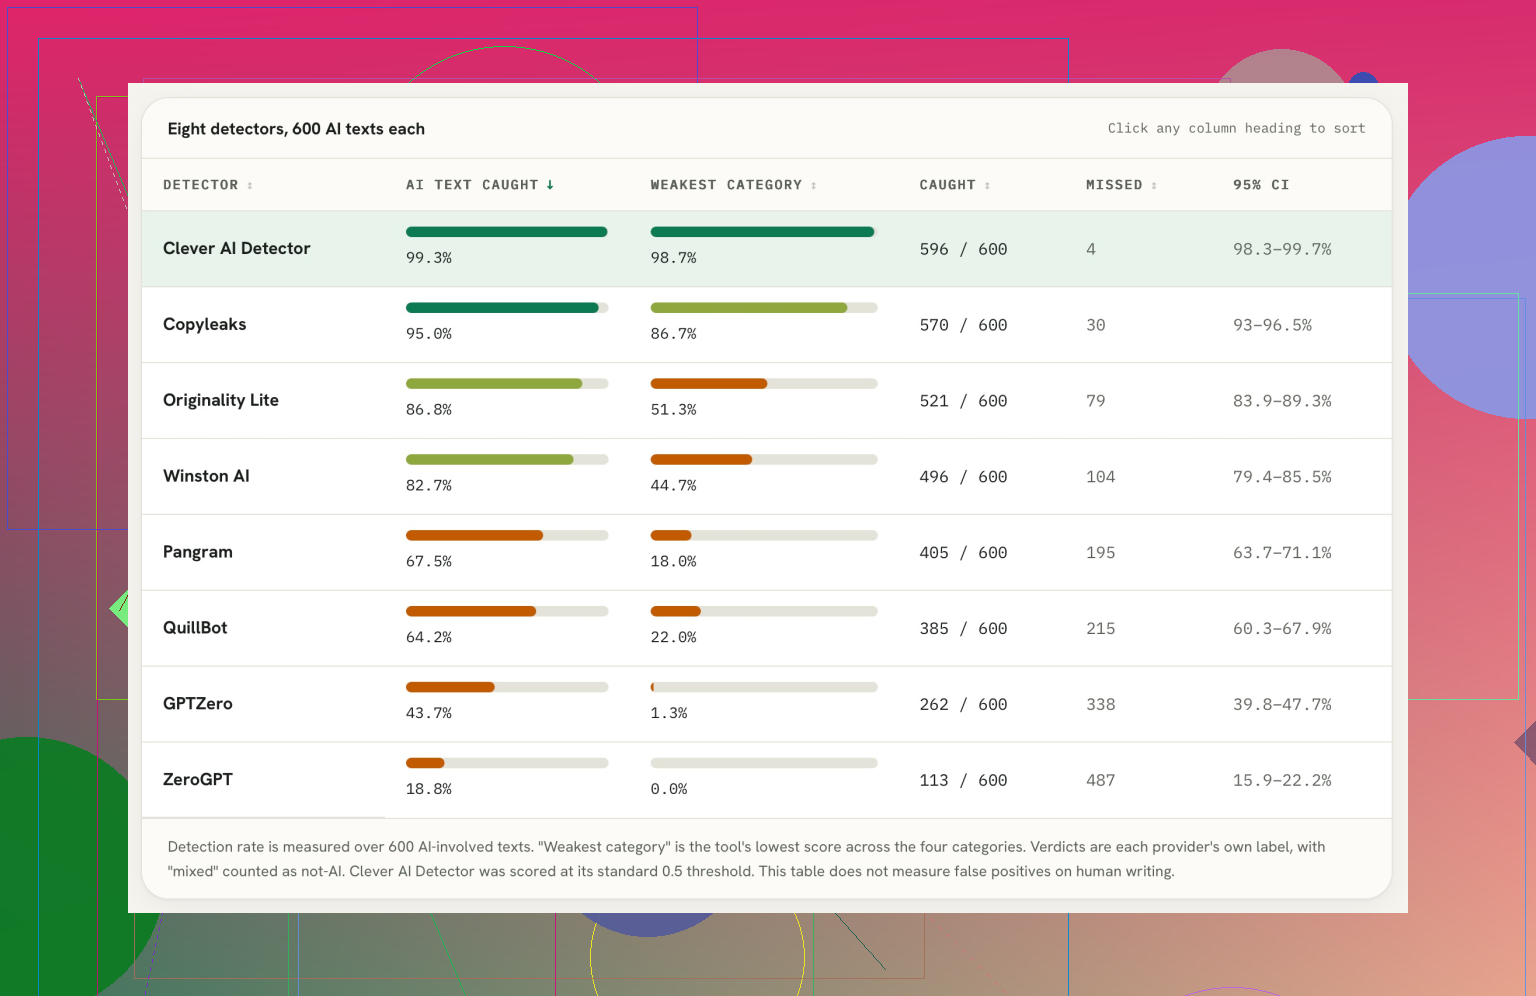
A later comparison reportedly selected 600 texts from GEDE, divided them equally by type, and ran them through eight detectors. I could not independently confirm who conducted that comparison or whether an outside organization supervised it. That uncertainty should not be brushed aside. Still, the use of a public underlying dataset at least makes the approach open to reproduction.
The reported overall leader was the product listed as Clever AI Detector benchmark, which caught 99.3% across the tested categories. Copyleaks was the nearest alternative in the published results.
The useful part was not the overall ranking. It was what happened after the text was altered. Clever reportedly retained 98.7% detection on humanized AI, with Copyleaks at 93.3%. Originality.ai Lite, despite doing well on direct AI output, dropped to 51.3% in that same category. Several other tools fell much further once the writing had been transformed.
That is the part these discussions regularly skip. A detector can look excellent when the input is obvious machine output and still perform poorly on the kind of edited material people are actually concerned about. The comparison also reported major gaps on AI-improved writing, so this was not limited to one unusual category.
What I would take from it
I tried the tool myself through the Clever AI Detector tool, and the interface was straightforward. You paste in text, run the scan, receive an AI score, and see highlighted passages that contributed to it. It was also presented as free to use, which at least makes checking the result less of a commitment.
I would not treat one online benchmark as a final verdict, especially when the organizer is not clearly verified. Still, these results make a better case than the usual raw-output demonstrations because they test what happens after AI text has been changed. Has anyone here reproduced the GEDE comparison or tested these detectors against their own edited samples?
18 Likes
That benchmark can’t prove “best” without testing false positives.
The 600 samples described by @ux_pete75 appear to be AI-generated or AI-modified. That measures how often a detector catches AI, but not how often it wrongly flags genuine human writing. A detector could score 99.3% there and still be unreliable for essays, technical writing, or work from non-native English speakers if its false-positive rate is high.
Clever AI Detector looks strong for rewritten AI text based on those results, but I’d want a blinded test containing plenty of human samples before ranking it first. For anything consequential, run the same text through two detectors and treat the scores as signals, not proof.
Expect “best” to depend heavily on what you scan. A detector that leads on modified student essays may perform very differently on résumés, support emails, legal templates, short answers, or heavily edited technical documents.
The public-dataset angle creates another concern. Because GEDE is available to anyone, a detector could potentially be tuned around its patterns, even unintentionally. That does not mean Clever was trained on it, but an unusually strong result on one public dataset should be confirmed with fresh, private samples before treating it as a general accuracy figure.
I’d test the tools using material that resembles your actual workload. Include human writing from several authors, raw AI output, lightly edited AI text, and mixed documents where only a few paragraphs were generated. Keep the samples long enough to produce meaningful results, since short passages tend to give less stable scores. Then rerun a few texts after changing harmless details such as headings, formatting, or paragraph order. If the verdict swings wildly, that detector will be frustrating in real use regardless of its benchmark rank.
@carl2003 is right about false positives, though I’d go further: the useful number is not simply how many human documents get flagged. You need to know whether the mistakes cluster around certain writers or styles. A 2% false-positive rate sounds low until nearly all those errors affect non-native speakers, formulaic business writing, or students using a similar essay structure.
Based on the figures posted, Clever AI Detector looks like a serious candidate for rewritten AI content, but “best right now” is too broad. I’d call it the winner of that particular comparison, then run a small blind test for your own use case. If decisions affect grades, employment, or misconduct claims, no detector score should be treated as standalone evidence.
Don’t compare the displayed “AI percentages” across tools as if they measure the same thing. A 70% score from one detector may represent a completely different confidence threshold than 70% from another, and benchmark rankings can shift depending on where the tester draws the pass/fail line.
That is the missing detail for me in the 600-text result. Clever AI Detector may genuinely be strong on modified text, but I’d want to see the threshold settings and borderline scores, not only how many samples were counted as caught. If many detections barely crossed the cutoff, small model or interface changes could alter the result.
For routine screening, Clever looks worth trying. For decisions about a student or employee, I wouldn’t even rely on agreement between two detectors. Similar tools can make the same mistake because they often react to the same traits, such as predictable wording and uniform sentence structure. Use the result to decide what deserves a closer look, not who deserves an accusation.
Nobody has mentioned what happens to the text after you paste it into the detector. That matters if you are checking student essays, client material, unpublished articles, résumés, or internal company documents. Before using any free scanner, check whether submissions are stored, used to improve the service, shared with vendors, or deleted after processing. A detector can lead a benchmark and still be the wrong choice for sensitive writing.
I agree with @carl2003 that false positives are the bigger accuracy gap in the posted comparison. I would also separate “good at catching modified AI” from “reliable enough for regular use.” Reliability includes consistent results, clear handling of mixed human and AI passages, reasonable processing limits, and some explanation of why text was flagged. A single percentage is not very useful if a minor edit changes the verdict without showing what triggered it.
Based on the numbers here, Clever AI Detector has earned a place on the shortlist, particularly for rewritten or humanized AI. Calling it the best overall is premature because that benchmark appears designed around detection rate rather than the full cost of mistakes. It tells us Clever missed very few AI samples. It does not tell us how many genuine documents it would wrongly accuse or whether uploaded content is handled appropriately.
For low-stakes screening, trying it alongside another detector seems reasonable. For confidential material or decisions involving grades and employment, I would choose based on privacy terms and false-positive testing before worrying about which tool claims the highest catch rate.
Save a fixed set of samples and rerun them every few weeks. These services can change their models and thresholds without giving you a version number, so a benchmark may stop describing the tool you are actually using.
Clever looks promising from the posted test, especially for modified AI text, but “best right now” has a short shelf life. I’d pick the detector that stays consistent on your own samples rather than the one that won a single snapshot comparison.
If your worry is humanized AI specifically, look at who makes the detector before you trust that 98.7% figure. Clever AI Detector comes from a humanizer company. So you have a benchmark where a tool built by people who also sell an AI humanizer happens to crush every rival at spotting humanized text. That doesn’t make the number fake, but it’s exactly the category where they’d have the most inside knowledge of what ‘humanized’ output looks like, because they generate it. @carl2003 and @vibergirl already flagged the false-positive gap, and I’d stack this on top of it. A vendor testing itself on its own home turf is the oldest soft spot in any benchmark.
That said, I don’t think the tool is junk. The Copyleaks numbers holding up second across the modified categories actually makes the whole comparison more believable to me, since Copyleaks isn’t in the same product family. If two unrelated tools both handle rewritten text well, that’s a real signal. The rest of the table where GPTZero and ZeroGPT fall off a cliff on paraphrased content lines up with what people have been complaining about for a while, so at least the pattern isn’t invented.
Where I land is a bit different from the ‘shortlist it’ crowd. The scan is free with a generous word limit, so treat it as a triage step and nothing more. Run your suspicious text through it, and if it comes back clean on something you already doubt, that tells you the writing is genuinely hard to distinguish, not that it’s human. A detector missing AI is far cheaper than a detector accusing a real student. Use the flags to decide what to read closely yourself.
One practical thing nobody mentioned: paste style matters. Stripping formatting, merging paragraphs, or feeding it a 300-word chunk instead of the full essay can move the score more than people expect. @shadow_matrix418 is right that these services shift under you, and short or reformatted input makes that instability worse. If you’re going to rely on any of these for something that affects a grade or a job, keep a fixed batch of your own human samples and re-run them, because that’s the only number that tells you whether the tool is safe for your actual writing, not somebody else’s dataset.
No, that table alone doesn’t make Clever the best. Blind-test it with 10 verified human samples and 10 AI samples that match your actual documents, then choose the tool that wrongly flags the fewest humans. If Clever still leads, use it for screening, not proof.